
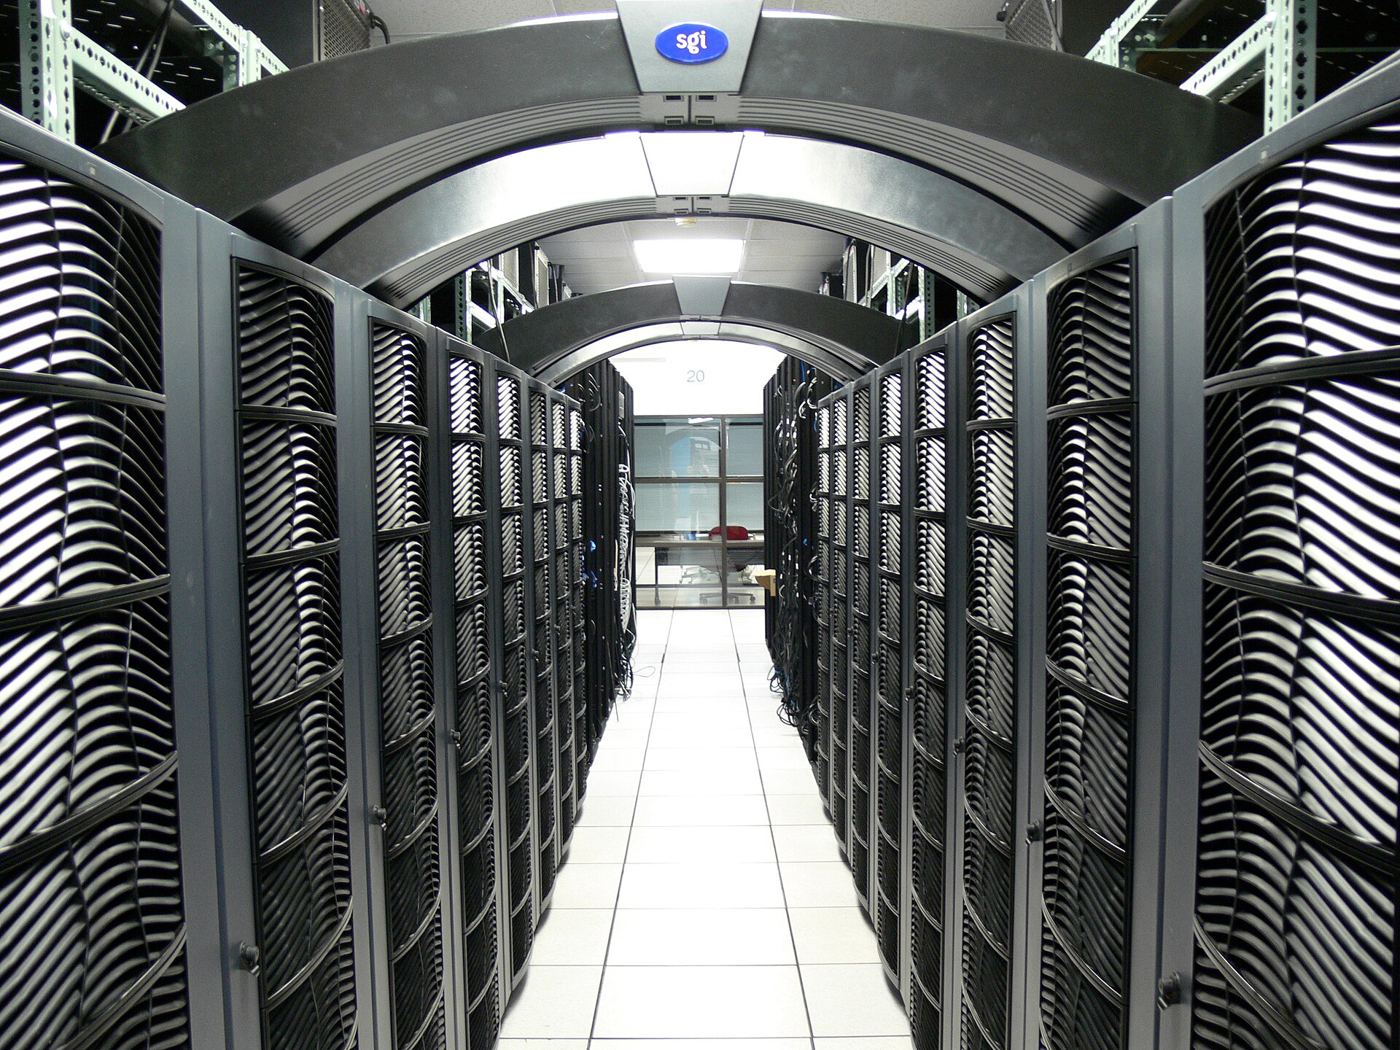
Many organisations now run their email, files, sales systems and customer support from cloud services, which makes a regional outage more than an inconvenience. Technology teams are responding by testing whether backups and spare capacity in a second region can actually take over when the main location fails, rather than assuming a diagram on paper will work under pressure. Those tests, sometimes called resilience drills, reveal ordinary problems such as expired credentials, missing data copies, slow recovery steps or staff who have never practised the handover. Finding those faults during a planned exercise is far cheaper than discovering them while customers are waiting and phones are ringing across a business that cannot process orders or answer basic enquiries. Regulators in finance and healthcare increasingly expect evidence of such testing rather than written assurances alone, asking firms to show when a recovery was last rehearsed, how long it took and what failed during the exercise in practice.
What the Evidence Shows
Cloud providers offer tools for copying data and restarting services elsewhere, but responsibility for choosing what must recover first still sits with each organisation. A hospital, a retailer and a small design studio will make different judgements about cost, downtime and which systems are truly essential. Specialists therefore recommend short, regular tests focused on one service at a time, with clear records of what worked and what needs fixing. The goal is not to prepare for every imaginable disaster, but to remove single points of failure that are already known. In a working life that depends on remote systems, confidence comes from having rehearsed the bad day before it arrives. Smaller businesses can start simply, by checking that backups restore correctly, that contact lists are current and that one essential service can run from an alternative location, building confidence step by step without buying every resilience tool available. Reporting and analysis from sources such as MIT Technology Review track the same developments, and specialists following multi-region cloud resilience say the direction is now consistent across independent lines of evidence.
The Wider Context
The wider context is an industry learning to ship capability and restraint together. Products built around multi-region cloud resilience now launch with safety evaluations, usage data and rollback plans as standard, because enterprise buyers and regulators ask for them in the first meeting. Companies that treated those questions as friction are discovering they have become the purchase criteria.
What Happens Next
What happens next for multi-region cloud resilience depends less on another breakthrough than on the unglamorous work of reliability, pricing and support. The buyers evaluating it now are not enthusiasts; they are operators with budgets and auditors, and their checklists will decide the timeline. On the evidence of the current pilots, the technology has earned the right to be judged by them. You can follow related developments in our coverage of technology.
There is a practical lesson in all of this for readers deciding what to do today. Start with the verified facts, be wary of anyone promising certainty, and prefer reversible steps while the evidence is still developing. Circumstances differ by country, income and personal situation, so general guidance should always be weighed against your own context before you act on it in any significant or lasting way.
